Never Underestimate the Power of bash
Prologue
At work, we often have to wrestle with logs of staggering volume. Sometimes we read logs to chase down a bug in the software; more often, we read them to extract something useful — data that can feed behavior analysis, anomaly detection, or even data recovery.
This weekend was busy at home, so in fits and starts I worked on a log parser. It isn’t hard to describe: parse tens of gigabytes of log files, extract some specific data, and store it in a database. The log format is fixed — standard tsv — so parsing a single record is trivial. But it isn’t simple either: the hundred-odd files are stored as gzip on AWS S3, and processing them efficiently is not so easy.
The most obvious approach is to write a Spark job. In the Spark ecosystem, handling a pile of gzip files is easy — a few dozen lines of code will do it. But what if there’s no Spark cluster ready at hand? You can’t very well spin up a Spark cluster just for a task like this. Let’s set that option aside for now.
The second approach is to use a language that supports streaming well. S3 itself handles streams beautifully — each file can be read chunk by chunk, the chunks handed to a streaming-capable gzip module for decompression, and then each line of the decompressed data parsed as tsv and written to the database. This sounds simple, but the small problems pile up in practice — especially in gzip decompression. If a chunk’s decompressed output ends mid-line, handling that gracefully is a real headache.
The third approach is a one-shot aws s3 sync to copy the files to be processed locally, then gunzip them one by one, and finally parse each line as tsv and write the results to the database.
Approach 2’s problem is code complexity; approach 3’s code is simple but its operability is poor — aside from eating an enormous amount of disk space, the back-and-forth reading and writing of files would dramatically slow down the whole process.
Is there a way to combine the strengths of approaches 2 and 3?
There is! We only need a few lines of bash, plus a line parser written in a few dozen lines of code.
Using bash and pipes
The bash code looks like this:
#!/bin/bash

BUCKET=tubitv-awesome-logs
PREFIX=${1:-20171111}

trap ctrl_c INT
function ctrl_c() {
  echo "** User stopped the process with CTRL-C"
  exit $?
}

for key in `aws s3api list-objects --bucket $BUCKET --prefix $PREFIX | jq -r '.Contents[].Key'`
do
  sleep 1
  aws s3 cp s3://$BUCKET/$key - | gunzip -c | log_parser
done
This bash script takes two arguments — the S3 bucket and prefix — and falls back to defaults if they aren’t provided. Then we use aws s3api list-objects --bucket $BUCKET --prefix $PREFIX to fetch all objects in the bucket that contain the prefix. s3api returns JSON, and we can parse it with jq to get each object’s Key — that is, its filename. Note that we use a pipe here: the aws CLI’s result is piped into jq.
A brief note on the concept of a pipe. In Unix, a program’s output, absent any other specification, goes into a bit of memory called stdout. The pipe operator takes the stdout of the previous program and feeds it into the stdin of the next.
For each key we get, we loop and process it — how?
- First,
aws s3 cp s3://$BUCKET/$key -. We copy the file in question to stdout. The “-” here denotes stdout. - Next, we pipe each copied chunk into
gunzip -c. gunzip processes the data in stdin and decompresses it to stdout — the-chere tells gunzip to output to stdout. - Finally, we pipe gunzip’s output into our own
log_parser. We just need to write log_parser properly so that it reads data from stdin line by line.
log_parser can be written in any language; since the problem’s scope has been massively reduced by the bash script, it’s very simple to write. Here’s an Elixir example (details of tsv parsing omitted):
defp parse do
  case IO.read(:stdio, :line) do
    :eof -> :ok
    {:error, reason} -> IO.puts "Error: #{reason}"
    line ->
      try do
        line
        |> parse_line()
        |> process()
      rescue
        e -> IO.puts("Cannot parse: #{line}. error: #{inspect e}")
      end
      parse()
  end
end
This code reads one line from stdin; if it hits EOF, it stops; otherwise, it gets a line of data. We just process that line.
Beautiful, isn’t it? This is the wonder of Unix — when you do one thing and do it well, the whole ecosystem rewards you.
Simple? Simple enough. But look back at the earlier bash script: when your machine has 16 cores, we’re only able to saturate one to process the data, and deep down we’re still dissatisfied with that simplicity. Can we process the data concurrently?
Using xargs to parallelize the work
No problem. We don’t need to change log_parser at all — we just tweak the bash script a little:
#!/bin/bash

BUCKET=tubitv-awesome-logs
PREFIX=${1:-20171111}

aws s3api list-objects --bucket $BUCKET --prefix $PREFIX | jq -r '.Contents[].Key' | xargs -n1 -P8 -I{} ./process_one.sh {}
The main body of the previous bash script is unchanged; we just use xargs -P8 to pass the individual arguments to a new script, process_one.sh, for parallel processing, with a parallelism of 8. Of course, you can swap in sysctl -n hw.ncpu (osx) or nproc --all (linux) to use the actual core count.
process_one.sh is trivial:
#!/bin/bash

BUCKET=tubitv-awesome-logs
KEY=$1

aws s3 cp s3://$BUCKET/$KEY - | gunzip -c | edgecast_parser
After this simple change, CPU utilization shoots right up:
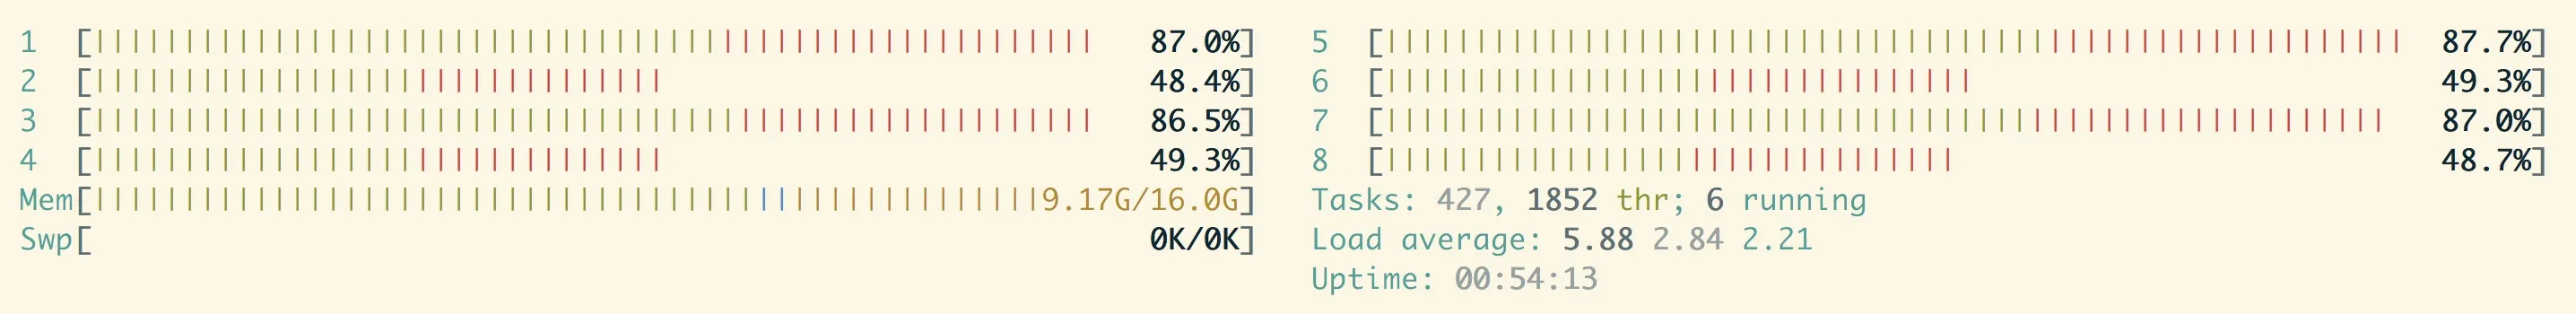
So far, I’ve written 65 lines of Elixir to parse the tsv, 18 lines of bash to glue everything together, and run it concurrently on a single machine. Nice and powerful. Had I written it all in Elixir, with the same functionality and the same capabilities, I’d probably have needed several hundred lines of code. In fact, on the weekend I tinkered with approach 2 and spent a huge amount of effort — pulled in three or four extra libraries, even patched one library (Elixir doesn’t have a well-wrapped streaming-capable gunzip library) — and the code was still only half done. Today it took a little over an hour to get the above approach working, cleanly and beautifully.
Some will say that this kind of single-machine concurrency still has a processing bottleneck — and honestly, if the problem really reaches that point, it’s best solved with Spark. That said, an Erlang cluster is also a fine alternative. You can form a cluster of Elixir processes on a set of machines, have one node publish each node’s bucket and prefix to process, and then each node runs the bash script above. When the number of machines in the cluster is on the order of several dozen, this approach is also a viable option.


